DP-203 — Free Practice Questions
10 free sample questions from a bank of 444, with the correct answers and explanations. No signup required — start practising right now.
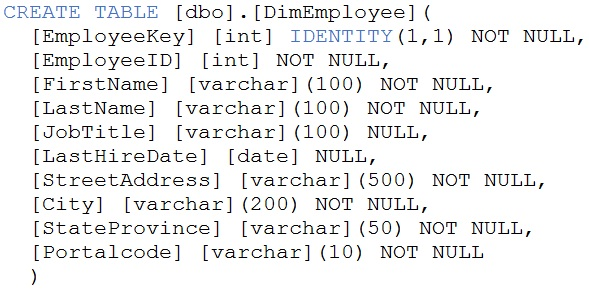
1You have a table in an Azure Synapse Analytics dedicated SQL pool. The table was created by using the following Transact-SQL statement. You need to alter the table to meet the following requirements:
✑ Ensure that users can identify the current manager of employees.
✑ Support creating an employee reporting hierarchy for your entire company.
✑ Provide fast lookup of the managers' attributes such as name and job title.
Which column should you add to the table?
- [ManagerEmployeeID] [smallint] NULL
- [ManagerEmployeeKey] [smallint] NULL
- [ManagerEmployeeKey] [int] NULL
- [ManagerName] [varchar](200) NULL
Answer: C
2HOTSPOT -
You have an Azure Data Lake Storage Gen2 container.
Data is ingested into the container, and then transformed by a data integration application. The data is NOT modified after that. Users can read files in the container but cannot modify the files.
You need to design a data archiving solution that meets the following requirements:
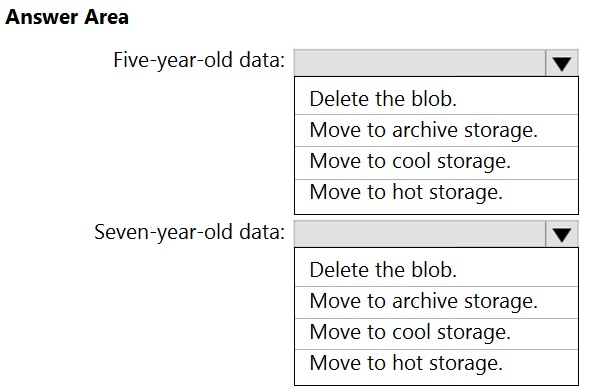
✑ New data is accessed frequently and must be available as quickly as possible.
✑ Data that is older than five years is accessed infrequently but must be available within one second when requested.
✑ Data that is older than seven years is NOT accessed. After seven years, the data must be persisted at the lowest cost possible.
✑ Costs must be minimized while maintaining the required availability.
How should you manage the data? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point
Hot Area:
Answer:
3You are implementing a star schema in an Azure Synapse Analytics dedicated SQL pool.
You plan to create a table named DimProduct.
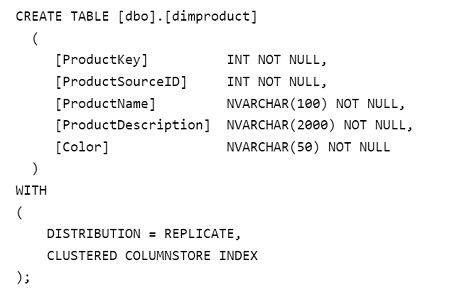
DimProduct must be a Type 3 slowly changing dimension (SCD) table that meets the following requirements:
• The values in two columns named ProductKey and ProductSourceID will remain the same.
• The values in three columns named ProductName, ProductDescription, and Color can change.
You need to add additional columns to complete the following table definition. Which three columns should you add? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
- [EffectiveStartDate] [datetime] NOT NULL
- [EffectiveEndDate] [datetime] NOT NULL
- [OriginalProductDescription] NVARCHAR(2000) NOT NULL
- [IsCurrentRow] [bit] NOT NULL
- [OriginalColor] NVARCHAR(50) NOT NULL
- [OriginalProductName] NVARCHAR(100) NULL
Answer: C, E, F
4HOTSPOT
-
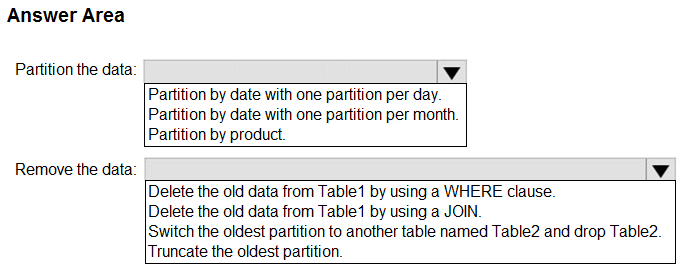
You have an Azure Synapse Analytics dedicated SQL pool named Pool1. Pool1 contains a fact table named Table1. Table1 contains sales data. Sixty-five million rows of data are added to Table1 monthly.
At the end of each month, you need to remove data that is older than 36 months. The solution must minimize how long it takes to remove the data.
How should you partition Table1, and how should you remove the old data? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
5You have an Azure subscription that contains an Azure Synapse Analytics serverless SQL pool.
You execute the following query. Where will the rows returned by the query be stored?
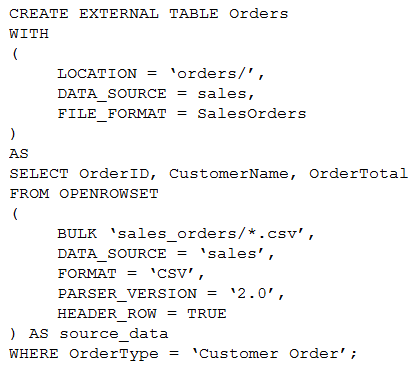
- in a file in a data lake
- in a relational database
- in a global temporary table
- in a session temporary table
Answer: A
6You are deploying a lake database by using an Azure Synapse database template.
You need to add additional tables to the database. The solution must use the same grouping method as the template tables.
Which grouping method should you use?
- partition style
- business area
- size
- facts and dimensions
Answer: B
7You have an Azure data factory connected to a Git repository that contains the following branches:
• main: Collaboration branch
• abc: Feature branch
• xyz: Feature branch
You save changes to a pipeline in the xyz branch.
You need to publish the changes to the live service.
What should you do first?
- Publish the data factory.
- Create a pull request to merge the changes into the main branch.
- Create a pull request to merge the changes into the abc branch.
- Push the code to a remote origin.
Answer: B
8Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an Azure subscription that contains an Azure data factory named ADF1.
From Azure Data Factory Studio, you build a complex data pipeline in ADF1.
You discover that the Save button is unavailable, and there are validation errors that prevent the pipeline from being published.
You need to ensure that you can save the logic of the pipeline.
Solution: You enable Git integration for ADF1.
Does this meet the goal?
- Yes
- No
Answer: A
9Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an Azure subscription that contains an Azure data factory named ADF1.
From Azure Data Factory Studio, you build a complex data pipeline in ADF1.
You discover that the Save button is unavailable, and there are validation errors that prevent the pipeline from being published.
You need to ensure that you can save the logic of the pipeline.
Solution: You view the JSON code representation of the resource and copy the JSON to a file.
Does this meet the goal?
- Yes
- No
Answer: A
10Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an Azure subscription that contains an Azure data factory named ADF1.
From Azure Data Factory Studio, you build a complex data pipeline in ADF1.
You discover that the Save button is unavailable, and there are validation errors that prevent the pipeline from being published.
You need to ensure that you can save the logic of the pipeline.
Solution: You export ADF1 as an Azure Resource Manager (ARM) template.
Does this meet the goal?
- Yes
- No
Answer: B
Want the full bank of 444 questions for DP-203? See all practice exams.