Certified Data Engineer Professional — Free Practice Questions
10 free sample questions from a bank of 141, with the correct answers and explanations. No signup required — start practising right now.
- date = spark.conf.get("date")
- input_dict = input() date= input_dict["date"]
- import sys date = sys.argv[1]
- date = dbutils.notebooks.getParam("date")
- dbutils.widgets.text("date", "null") date = dbutils.widgets.get("date")
The short version
E — Widgets carry Jobs parameters into notebooks. Passing a Jobs API parameter named date requires declaring a widget of the same name and reading it with widgets.get, which is exactly what option E does for this batch path.
Key concepts in this question
- dbutils.widgets: notebook-scoped input mechanism that declares typed widgets such as text, dropdown, combobox and multiselect for parameterized execution.
- Jobs API parameters: key value pairs supplied at run submit time that become available inside the notebook only when a matching widget has been declared.
- dbutils.notebooks.getParam: API used for notebook workflows where one notebook calls another with arguments, not for top level Jobs parameter injection.
- spark.conf: Spark configuration store for engine settings, unrelated to Jobs parameter passing and unable to surface user supplied date values.
Why E is correct
Option E first declares a text widget named date with a default of null, then reads it with widgets.get into a Python variable. That two step pattern is the documented contract for Jobs parameterized notebooks, because the Jobs scheduler populates widget values before execution starts.
Why the others are wrong
- A. spark.conf only exposes Spark and Hadoop configuration, so it cannot see a Jobs parameter named date and returns missing key behavior.
- B. bare input reads from stdin in interactive consoles, which does not exist on automated clusters and is never populated by the Jobs API.
- C. sys.argv reflects JVM launch arguments for plain Python processes, not Databricks notebook task parameters injected through widgets.
- D. notebooks.getParam serves notebook to notebook calls, not top level Jobs scheduling use.
Certified-Data-Engineer-Professional exam tip
Remember the pairing rule: Jobs parameter needs matching widget, cross notebook call needs getParam, plain config needs spark.conf,.
- All records are cached to an operational database and then the filter is applied
- The Parquet file footers are scanned for min and max statistics for the latitude column
- All records are cached to attached storage and then the filter is applied
- The Delta log is scanned for min and max statistics for the latitude column
- The Hive metastore is scanned for min and max statistics for the latitude column
The short version
D — Delta log statistics drive file skipping. The optimizer consults min and max values recorded per file in the transaction log, so it can skip files whose latitude range cannot satisfy greater than 66.3 without opening them.
Key concepts in this question
- Delta transaction log: ordered JSON journal that records every commit, add and remove action plus per file statistics used for correctness and optimization.
- Data skipping: pruning technique that compares query predicates against stored min max statistics to avoid reading irrelevant Parquet files.
- Parquet footers: embedded metadata inside each file that holds column statistics, read only after the engine has already decided to open that file.
- Partitioning versus statistics: partition columns allow directory pruning, while non partition columns like latitude still benefit from file level min max skipping.
Why D is correct
Delta Lake writes statistics for roughly the first 32 columns of each data file into the log, including record count, minima, maxima and null counts. For a filter on latitude, the optimizer scans those log entries and retains only files whose interval overlaps the predicate, which reduces I O for selective queries such as Arctic Circle filtering.
Why the others are wrong
- A. no operational database caches full tables for filtering, Delta reads from cloud storage with log driven pruning.
- B. footer statistics exist but are only read after file selection, so they do not decide which files to load at plan time.
- C. attached storage caching may speed repeated reads, but it is not the mechanism that identifies candidate files for a predicate.
- E. the metastore holds table level catalog data, not per file min max pruning stats.
Certified-Data-Engineer-Professional exam tip
When a question asks how the engine identifies files to load, choose Delta log min max, when it asks what happens inside an opened
- "Manage" permissions should be set on a secret key mapped to those credentials that will be used by a given team.
- "Read" permissions should be set on a secret key mapped to those credentials that will be used by a given team.
- "Read" permissions should be set on a secret scope containing only those credentials that will be used by a given team.
- "Manage" permissions should be set on a secret scope containing only those credentials that will be used by a given team. No additional configuration is necessary as long as all users are configured as administrators in the workspace where secrets have been added.
The short version
C — Read on the team scope gives least privilege. Granting Read on a secret scope that holds only that team credentials lets jobs retrieve values at runtime without permitting scope administration or cross team access.
Key concepts in this question
- Secret scopes: named collections that group related secrets behind a single access control boundary in Databricks.
- Secret keys: individual entries inside a scope holding one credential value such as a password or token for the external database.
- Read versus Manage: Read allows listing and reading secret values for use in code, while Manage allows changing ACLs and deleting or writing secrets.
- Group mapped credentials: separate logins per team aligned to existing Databricks groups, requiring isolation so each team sees only its own login.
Why C is correct
A scope scoped to one team plus Read for that team group satisfies least privilege cleanly. The team code can reference the secret in connection logic, while members cannot edit the scope, add keys, or grant others access. Managing one ACL on the scope scales better than managing many key level ACLs and prevents accidental exposure when new keys are added for rotation.
Why the others are wrong
- A. Manage on a key over grants administrative control and still leaves scope level organization and future keys unprotected.
- B. Read on a key can technically work but fragments administration across keys and fails to isolate future rotated credentials cleanly.
- D. Manage on a scope over grants administration to ordinary users, and making everyone an admin violates least privilege entirely.
Certified-Data-Engineer-Professional exam tip
Memorize the matrix: use needs Read, administration needs Manage, isolate teams with separate scopes, and always prefer scope level Read for group mapped external credentials.
- Size on Disk is < Size in Memory
- The RDD Block Name includes the “*” annotation signaling a failure to cache
- Size on Disk is > 0
- The number of Cached Partitions > the number of Spark Partitions
- On Heap Memory Usage is within 75% of Off Heap Memory Usage
The short version
C — Any spill to disk means MEMORY_ONLY failed. With pure in memory caching, Size on Disk above zero proves partitions did not fit in memory and were evicted, forcing slower recomputation or disk reads.
Key concepts in this question
- MEMORY_ONLY storage level: Spark persistence mode that keeps deserialized or serialized partitions in memory only and recomputes dropped partitions rather than spilling them.
- Storage tab: Spark UI page showing RDD and DataFrame cache status including fraction cached, size in memory, size on disk and partition counts.
- Size in Memory versus Size on Disk: complementary metrics that reveal where cached blocks actually reside after execution pressure and eviction.
- Eviction and recompute cost: when memory fills, MEMORY_ONLY drops partitions, causing repeated recomputation and longer stage times on reuse.
Why C is correct
MEMORY_ONLY by definition never writes to disk by design, so a healthy fully cached table shows Size on Disk equal to zero. A positive Size on Disk indicates the table did not actually stay MEMORY_ONLY in practice, either because the storage level was not honored or because blocks spilled under memory pressure in the UI reporting.
Why the others are wrong
- A. Size on Disk less than Size in Memory is normal for a healthy cache and does not indicate a problem by itself.
- B. the star annotation is not a standard Storage tab failure marker for caching, so it cannot be used as a diagnostic.
- D. cached partitions exceeding Spark partitions is not expected behavior and does not describe typical under performance from eviction.
- E. heap versus off heap ratio describes executor layout, not cache spill status.
Certified-Data-Engineer-Professional exam tip
Link storage level to expected metric: MEMORY_ONLY must show zero on disk, MEMORY_AND_DISK may show disk use normally, so only the first pattern proves a caching problem.
- %python
- // Databricks notebook source
- # Databricks notebook source
- -- Databricks notebook source
- # MAGIC %python
The short version
C — Python notebooks start with a Python comment marker. Exported source files begin with a language appropriate comment holding the notebook source tag, which is hash plus text for Python.
Key concepts in this question
- Notebook source export: plain text representation of Databricks notebooks where each cell is marked with magic comments for portability through repos.
- Language specific comment syntax: Python and R use hash, SQL uses double dash, Scala uses double slash to introduce the same source header.
- First line header: stable marker that tells the platform and version control integration that the file originated as a notebook.
- Cell magic: lines like MAGIC that prefix non default languages inside a notebook, distinct from the file level header.
Why C is correct
A Python notebook exported to source control shows hash Databricks notebook source as its very first line, because hash starts a comment in Python and therefore does not affect execution. The platform uses that exact line to recognize the file as a notebook on import, preserving cell boundaries that follow. SQL and Scala use their own comment tokens for the same logical header, which explains why each language has a different literal but identical meaning.
Why the others are wrong
- A. percent python sets a cell language inside mixed notebooks, it is not the file level export header.
- B. double slash is the Scala comment form of the header, incorrect for a Python notebook viewed as text.
- D. double dash is the SQL comment form of the header, incorrect for Python source files.
- E. hash MAGIC percent python appears inside cells to embed Python in non Python notebooks, not as the first export line.
Certified-Data-Engineer-Professional exam tip
Memorize the trio by comment style: hash for Python and R, double dash for SQL, double slash for Scala, and pick the line that matches the notebook language in the question.
- Makes it easier to automate your test suite
- Pinpoints errors in the building blocks of your application
- Provides testing coverage for all code paths and branches
- Closely simulates real world usage of your application
- Ensures code is optimized for a real-life workflow
The short version
D — End to end tests mirror real user journeys. Their defining value is exercising the full chain from input through dependent systems, revealing integration failures that isolated tests miss.
Key concepts in this question
- End to end testing: validation of complete workflows across UI, services, storage and network in a production like environment.
- Unit testing: focused checks on small building blocks in isolation that pinpoint logic errors quickly but miss cross component issues.
- Integration testing: checks of contracts between a subset of components, narrower than full user journey coverage.
- Coverage testing: systematic exercise of code paths and branches, a completeness metric rather than a realism benefit.
Why D is correct
End to end tests launch the application as a real user would, passing data through ingestion, processing, databases, networks and downstream consumers. That realism surfaces dependency mismatches, configuration gaps, permission errors and sequencing bugs that never appear when components are stubbed. While slower and harder to automate than unit tests, they provide confidence that the system works together in practice.
Why the others are wrong
- A. ease of automation is a strength of unit tests with small setup, end to end suites are typically slower and more brittle.
- B. pinpointing building block errors is the purpose of unit tests, end to end failures require extra triage to localize.
- C. exhaustive path and branch coverage is pursued with unit and white box methods, not with broad journey tests.
- E. optimization for real workflows concerns performance tuning, not the correctness assurance that defines end to end testing.
Certified-Data-Engineer-Professional exam tip
Map each benefit to its layer: real world simulation means end to end, pinpointing units means unit, contracts mean integration, all paths means coverage.
- The job_id and number of times the job has been run are concatenated and returned.
- The total number of jobs that have been run in the workspace.
- The number of times the job definition has been run in this workspace.
- The job_id is returned in this field.
- The globally unique ID of the newly triggered run.
The short version
E — run_id identifies one specific execution globally. The Jobs API returns a fresh unique run identifier for the newly created run, separate from the stable job definition identifier.
Key concepts in this question
- job_id: stable identifier for a job definition that persists across many executions and configuration edits.
- run_id: unique identifier assigned to each individual execution, used to query status, logs and task results for that attempt.
- Jobs run now semantics: submitting an existing job creates a new run object rather than mutating the definition, so tracking requires the new run key.
- Multi task runs: a single parent run contains child task runs, each with its own run identifier linked to the parent.
Why E is correct
When run now succeeds, the service allocates a new run record with a globally unique run_id and returns it to the caller. That value is the handle for subsequent get run, cancel run and task result calls for exactly that launch. It is not derived by concatenating counters and it is not the job_id echoed back, because job_id already exists and cannot distinguish retries or concurrent executions. Understanding this split is essential for orchestration code that launches jobs from the CLI.
Why the others are wrong
- A. run_id is an allocated unique key, not a string concatenation of job_id and execution count.
- B. workspace wide run counts are not exposed as run_id, which scopes to a single execution of a single job.
- C. per job execution counts are not the semantics, uniqueness is global and suitable for direct lookup.
- D. job_id appears in a separate field for definition identity, the run_id field never carries the job_id value.
Certified-Data-Engineer-Professional exam tip
Remember the pairing: job_id names the definition, run_id names the execution, and any question about tracking a triggered run wants the globally unique run identifier.
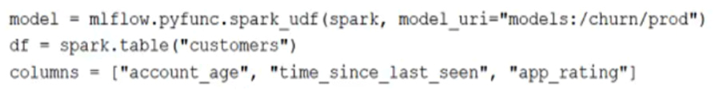
- df.map(lambda x:model(x[columns])).select("customer_id, predictions")
- df.select("customer_id", model(*columns).alias("predictions"))
- model.predict(df, columns)
- df.select("customer_id", pandas_udf(model, columns).alias("predictions"))
- df.apply(model, columns).select("customer_id, predictions")
The short version
B — MLflow Spark UDF applies per row with select. Loading an MLflow model as a Spark UDF lets you keep customer_id and compute predictions in one projection, yielding the required two column schema.
Key concepts in this question
- MLflow pyfunc as Spark UDF: spark.udf wrapper that exposes a logged model as a column function callable inside DataFrame operations.
- Column unpacking: passing a Python list of feature names with star syntax so each name becomes a separate UDF argument.
- Alias for output naming: renaming the computed expression to predictions to match the downstream contract of customer_id plus predictions.
- Distributed inference: executing the model on executors across partitions rather than collecting data to the driver for local scoring.
Why B is correct
Option B selects customer_id unchanged and evaluates the model UDF over the feature columns, aliasing the result as predictions. Spark handles type conversion and partitioning, returning a DataFrame with LONG key and DOUBLE prediction as requested. The pattern avoids driver bottlenecks and manual iteration, and it integrates with Catalyst optimization for batch scoring.
Why the others are wrong
- A. RDD map loses DataFrame schema and select syntax shown is invalid, so it cannot produce the typed two column result.
- C. model dot predict on a DataFrame is not the Spark UDF calling convention for logged pyfunc models in this context.
- D. wrapping the model redundantly in pandas_udf is unnecessary and the argument handling does not match the loaded UDF signature.
- E. DataFrame dot apply is not a valid distributed scoring API and the chained select cannot yield the stated schema.
Certified-Data-Engineer-Professional exam tip
For MLflow batch scoring questions, look for select with key plus model star columns aliased to predictions, and reject RDD map, bare predict and manual apply variants.
- Perform a batch read on the reviews_raw table and perform an insert-only merge using the natural composite key user_id, review_id, product_id, review_timestamp.
- Configure a Structured Streaming read against the reviews_raw table using the trigger once execution mode to process new records as a batch job.
- Use Delta Lake version history to get the difference between the latest version of reviews_raw and one version prior, then write these records to the next table.
- Filter all records in the reviews_raw table based on the review_timestamp; batch append those records produced in the last 48 hours.
- Reprocess all records in reviews_raw and overwrite the next table in the pipeline.
The short version
A — Insert-only merge is the cheapest way to propagate new plus late reviews. It deduplicates on the natural key without rescanning the downstream table, and it still catches moderator-delayed records that land days late.
Key concepts in this question
- Bronze to silver step: reviews_raw is append-only landing, the next table is deduplicated plus validated, so only newcomers should be merged.
- Late-arriving data: source paths are YYYY/MM/DD by processing date, but moderator approval delays some reviews, so date filters miss rows.
- Insert-only MERGE: Delta MERGE with WHEN NOT MATCHED THEN INSERT skips updates and deletes, avoiding a full table comparison.
- Batch versus streaming: trigger once adds checkpoint overhead that only pays off for continuous sources, not one nightly batch.
Why A is correct
A reads reviews_raw as a batch and merges on user_id plus review_id plus product_id plus review_timestamp, inserting only keys not already downstream. Because matching is on the key rather than recency or version position, delayed reviews are picked up when their files land while existing rows are skipped cheaply.
Why the others are wrong
- B. Trigger-once streaming adds checkpoint plus planning cost for an already bounded batch, with no correctness gain.
- C. Diffing the latest two versions breaks when ingestion commits multiple times or late data touches older partitions.
- D. Filtering on review_timestamp for 48 hours misses older delayed records and reprocesses recent duplicates.
- E. Reprocessing every row and overwriting the target maximizes scan plus shuffle plus write on each run.
Certified-Data-Engineer-Professional exam tip
Append-only bronze plus late arrivals plus deduped silver means insert-only MERGE on the natural key, never time filters.
- Before a Jobs cluster terminates, OPTIMIZE is executed on all tables modified during the most recent job.
- An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an OPTIMIZE job is executed toward a default of 1 GB.
- Data is queued in a messaging bus instead of committing data directly to memory; all data is committed from the messaging bus in one batch once the job is complete.
- Optimized writes use logical partitions instead of directory partitions; because partition boundaries are only represented in metadata, fewer small files are written.
- A shuffle occurs prior to writing to try to group similar data together resulting in fewer files instead of each executor writing multiple files based on directory partitions.
The short version
E — Optimized writes shuffle before the write to make fewer, larger files. Grouping by partition lets each executor write coalesced output instead of many small files, easing future reads.
Key concepts in this question
- Small-files problem: many tiny Parquet files inflate listing plus log plus planning overhead, so Databricks targets roughly 128 MB files.
- Pre-write shuffle: optimized writes add a shuffle by partition columns, trading some shuffle cost for far fewer files written.
- OPTIMIZE distinction: OPTIMIZE compacts files after they exist, while optimized writes reduce fragmentation at write time.
- Auto-compact distinction: post-commit compaction toward 1 GB is a separate mechanism, not the write-path shuffle itself.
Why E is correct
E matches the documented behavior: Spark shuffles rows so each partition lands together before commit, and executors write fewer large files instead of one small file per task per directory. That write-path shuffle is exactly what Databricks calls optimized writes, and its read gains outweigh the extra shuffle on most workloads.
Why the others are wrong
- A. No OPTIMIZE runs on cluster termination, termination only releases compute and leaves files untouched.
- B. Async post-write compaction toward 1 GB describes auto-compact, not the pre-write shuffle.
- C. Writes commit directly from executors through the Delta log, not via a staged messaging bus.
- D. Logical versus directory partitioning confuses clustering concepts, the feature does not change partition storage.
Certified-Data-Engineer-Professional exam tip
Writes means before commit with shuffle, OPTIMIZE plus auto-compact means after commit, that split answers file-sizing questions.
Want the full bank of 141 questions for Certified Data Engineer Professional? See all practice exams.